

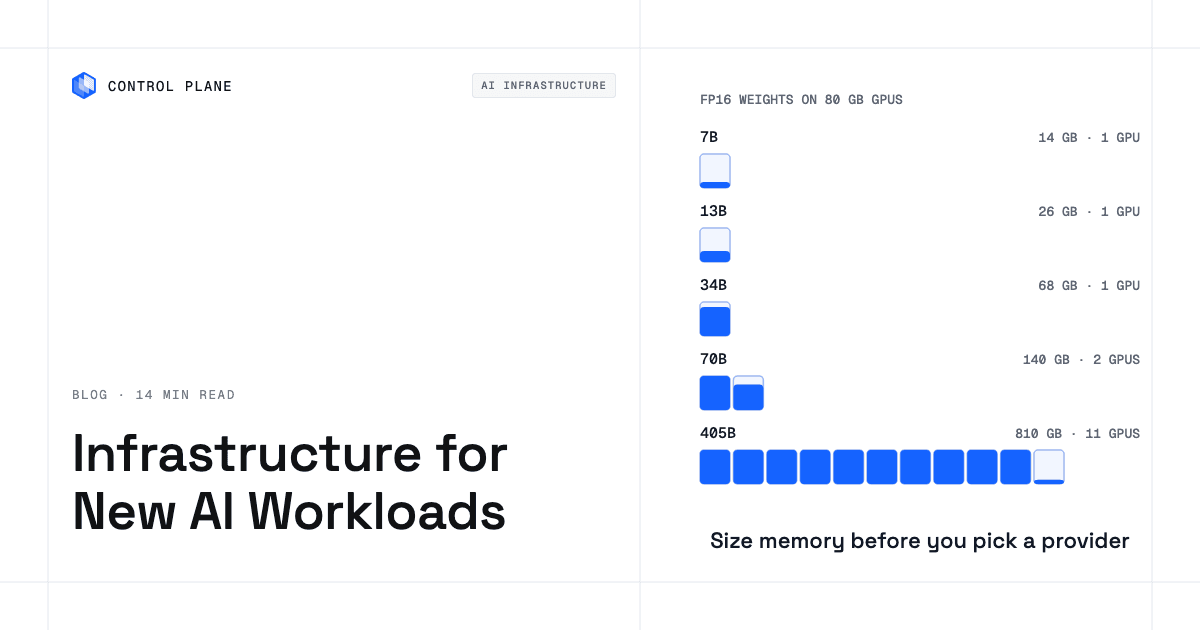
How to select infrastructure for new AI workloads: six workload types, a GPU memory sizing table, and where to run each, from APIs to your own GPUs.
Blog
From the Control Plane blog
Cloud-native engineering, multi-cloud strategy, and platform deep-dives.
All posts
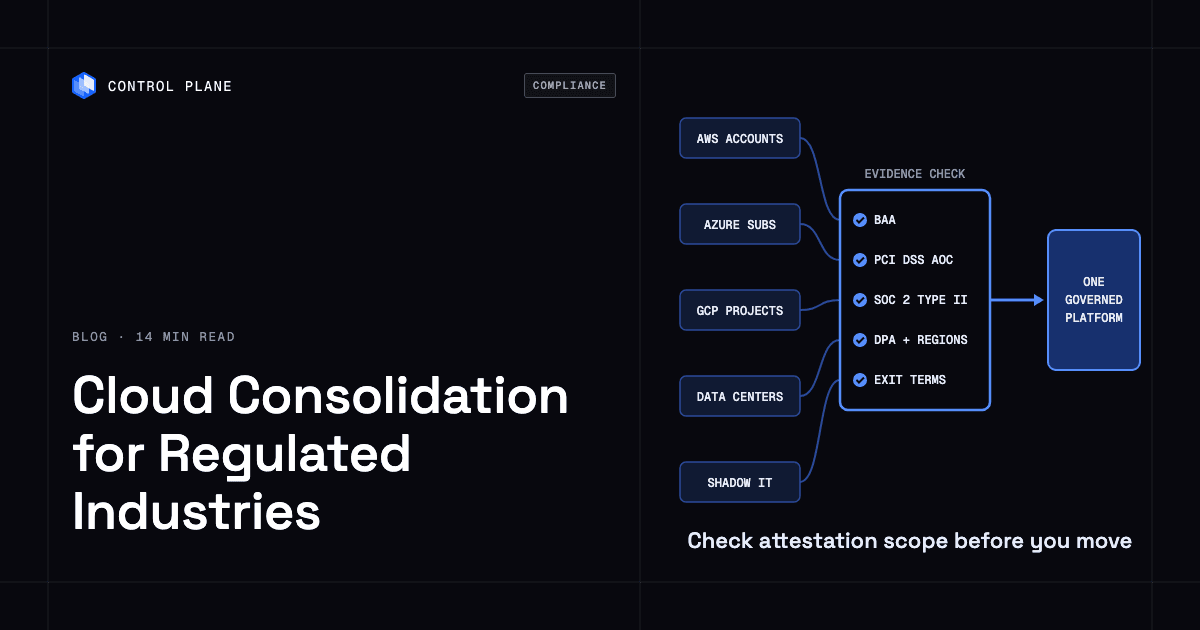
Which vendors specialize in regulated cloud consolidation for finance and healthcare, what each vendor type does, and the evidence to demand from each.
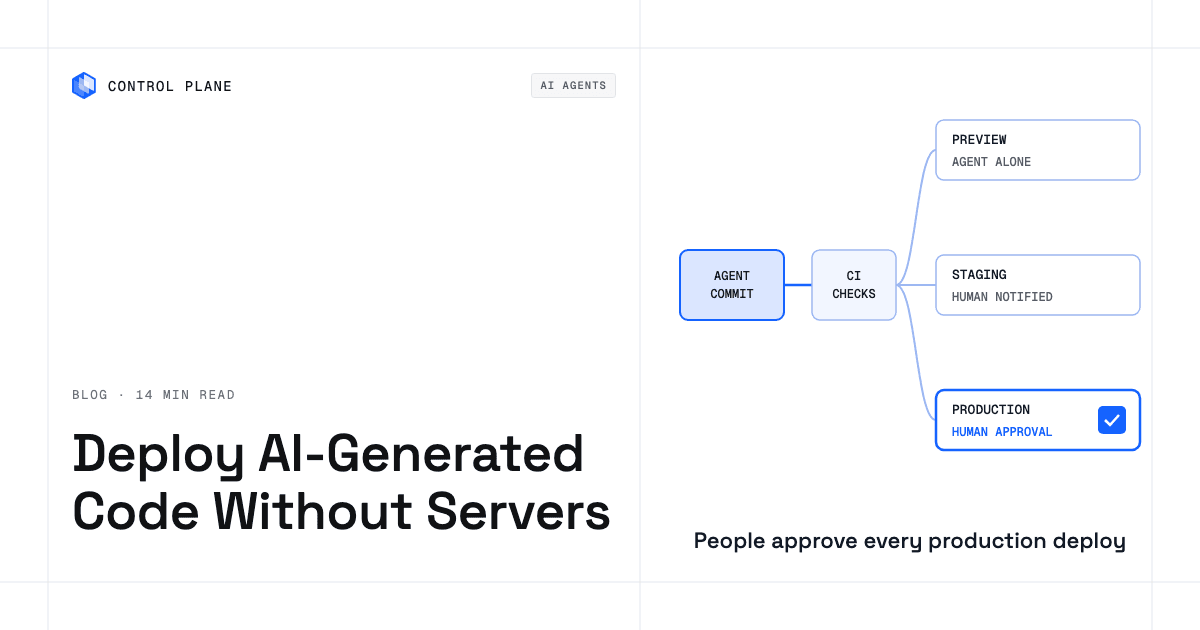
How to deploy code generated by AI agents without managing servers: deployment models, what agents may do alone, and a safe pipeline to production.
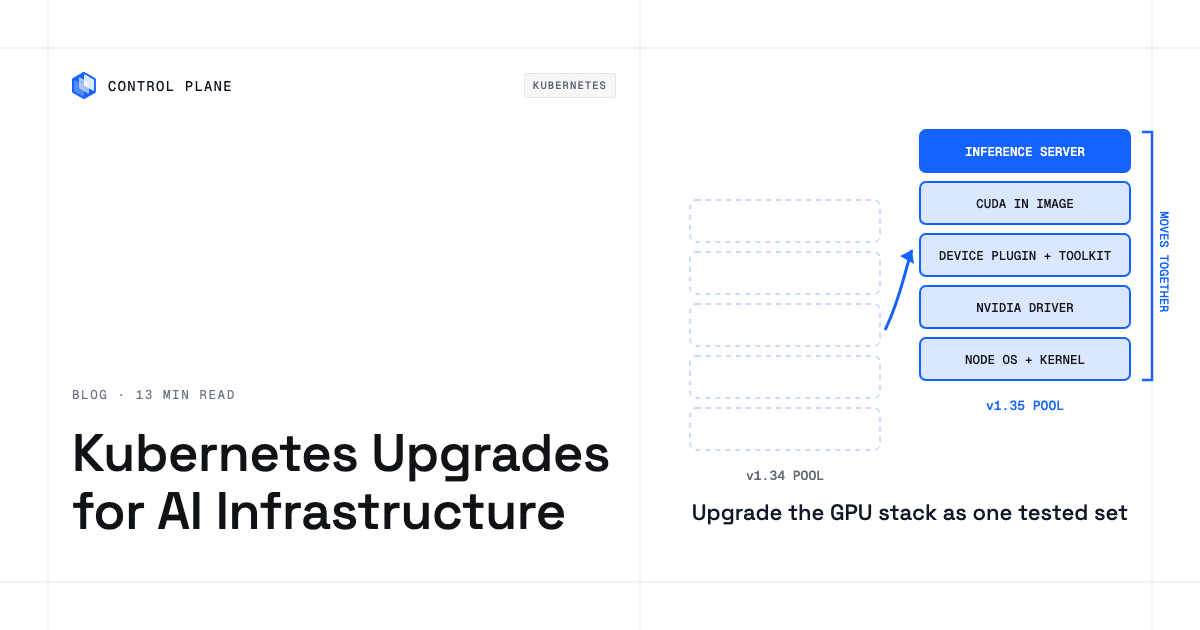
How to upgrade Kubernetes for AI workloads without downtime: EKS, GKE, and AKS upgrade mechanics, the GPU stack to move together, and compliance evidence.
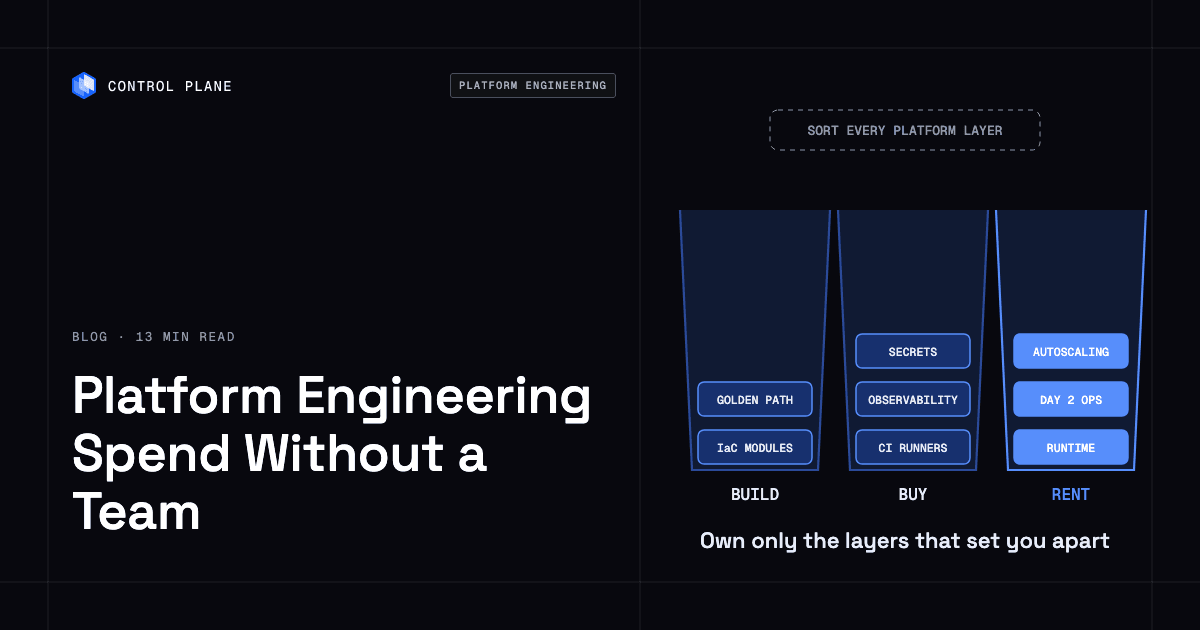
How to balance platform engineering spend without a platform team: a spend ledger, build-buy-rent by layer, and triggers for your first platform hire.
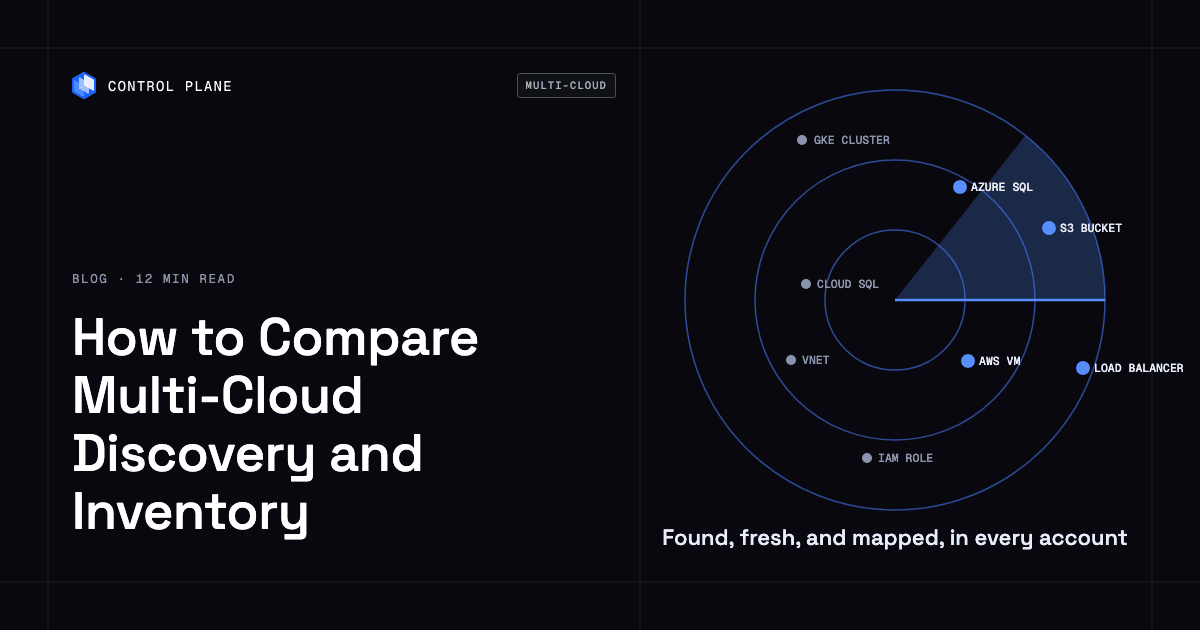
How to compare cloud discovery, inventory, and multi-cloud management tools: what native inventories give you, a weighted scorecard, and a PoC test plan.
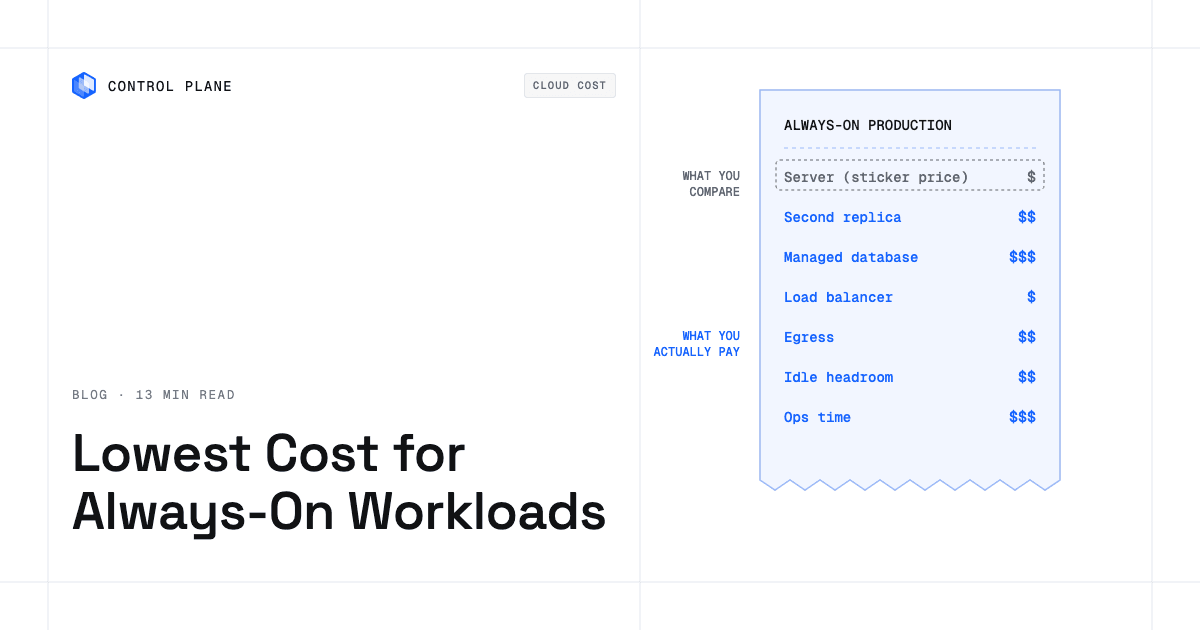
The lowest cost for always-on production is a full-stack question. What you pay for beyond the server price, by pricing model and workload shape.
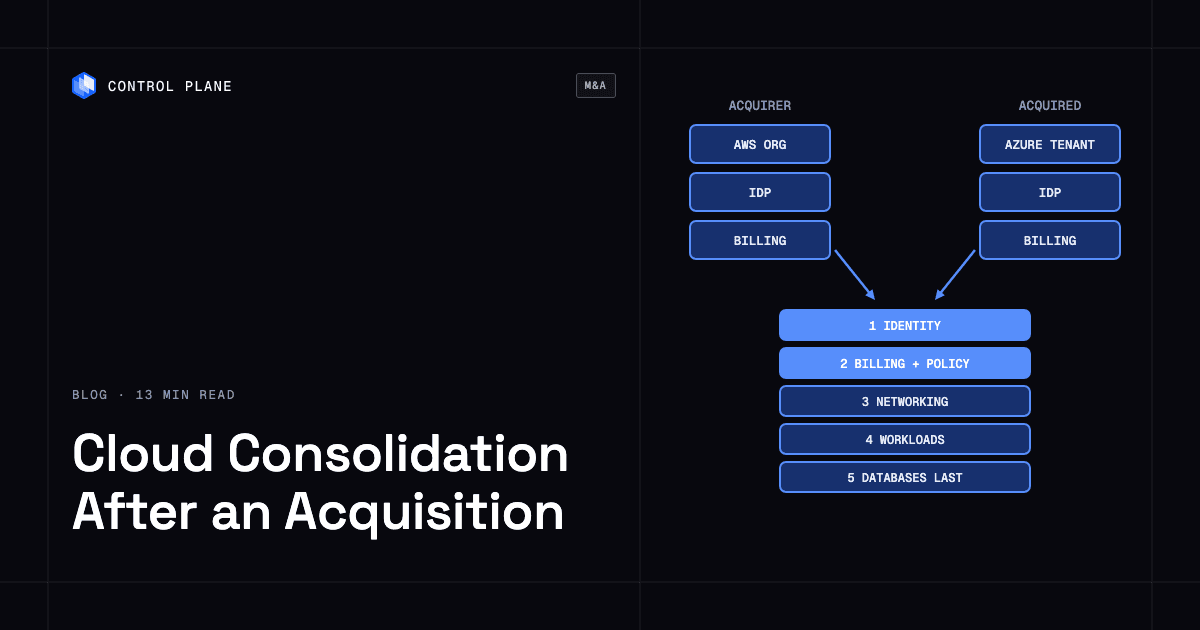
Consolidate cloud infrastructure after an acquisition in layers: what to merge by Day 1, 100, and 365, same-cloud moves, and which steps risk downtime.
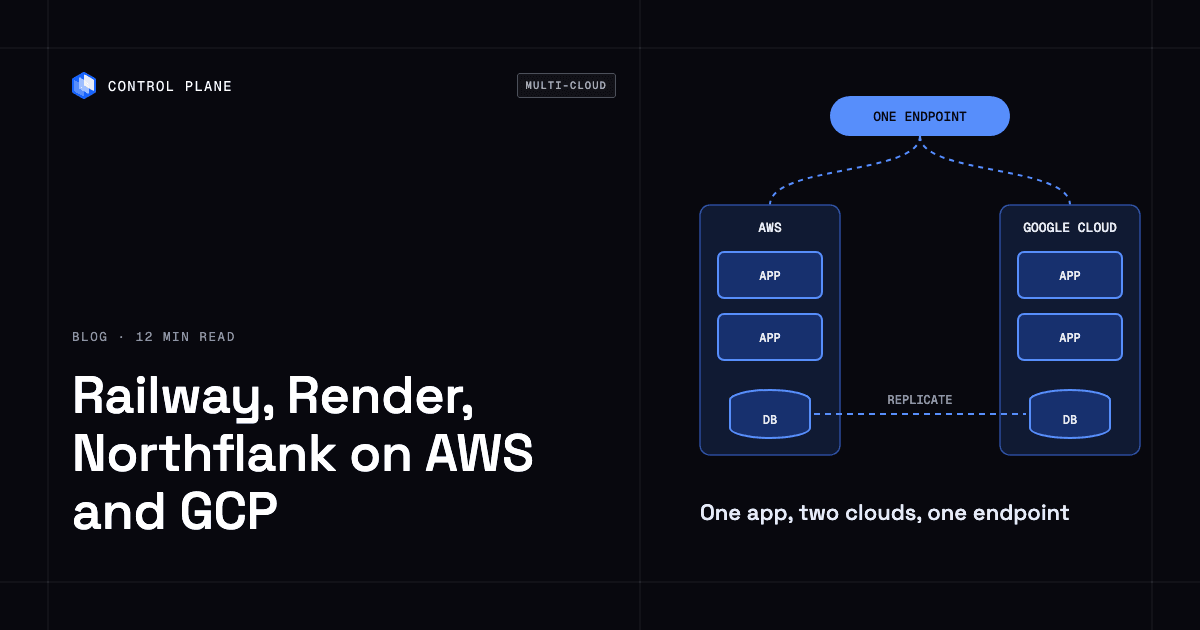
What Railway, Render, and Northflank document about running one app on AWS and Google Cloud, what you build yourself, and a step-by-step plan.
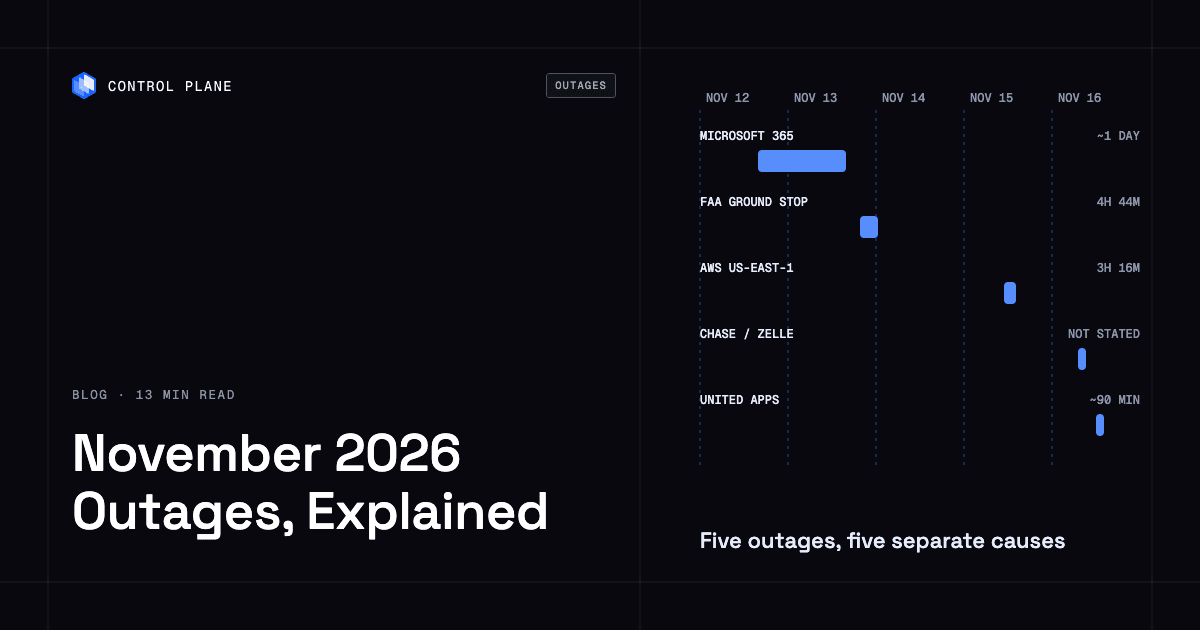
A sourced account of the November 2026 outages at Microsoft 365, the FAA, AWS, Chase, and United: what failed, how long, the causes, and the hoaxes.
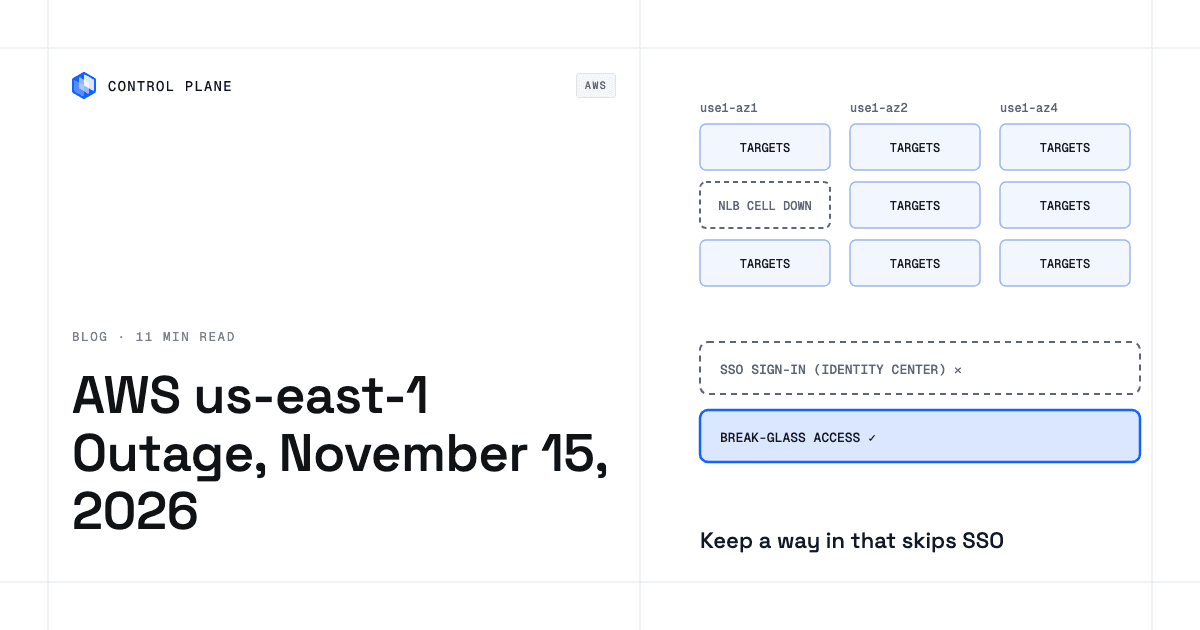
What failed in AWS us-east-1 on November 15, 2026, why sign-in and load balancers mattered, and a checklist for the next regional incident.
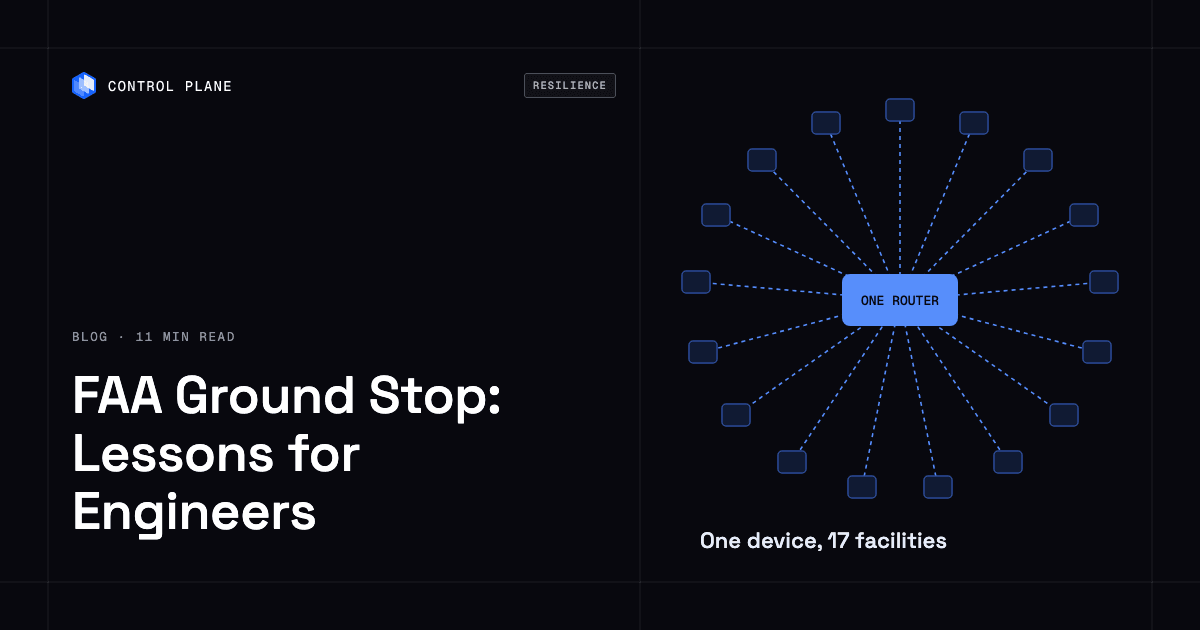
How a network flood disrupted US flights on November 13, 2026, why redundancy didn’t help, and a failure-domain checklist for software and cloud teams.