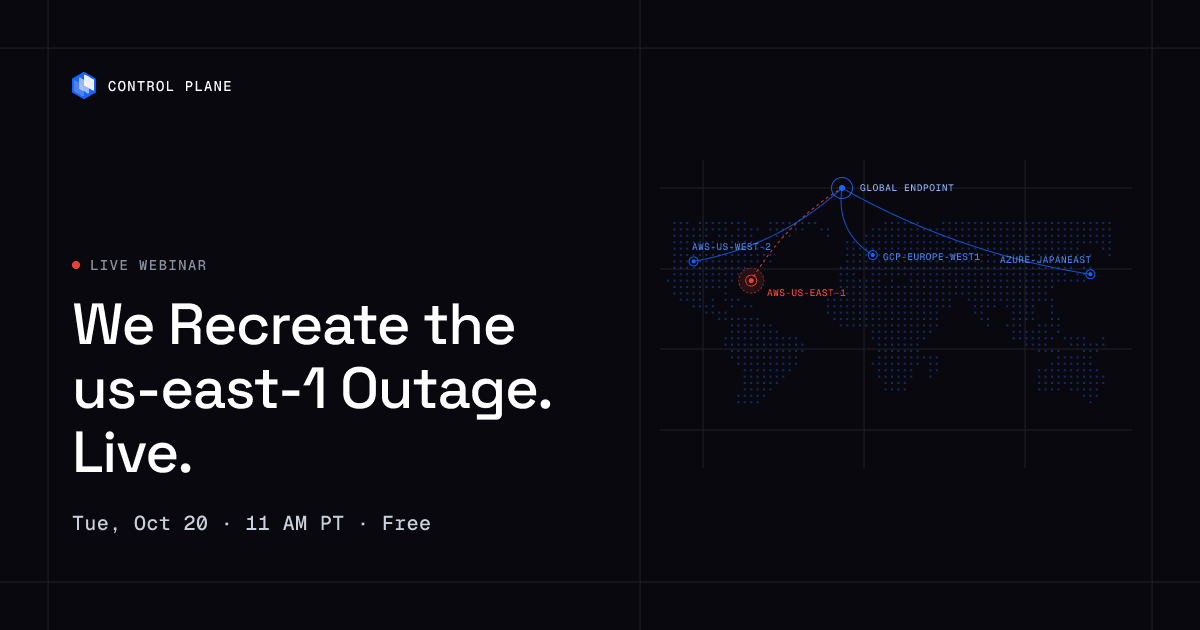
Live webinar: Tuesday, October 20, 2026, 11:00 AM PT. One year to the day after the AWS us-east-1 outage, we recreate the failure live and show what happens to an application running active-active across locations when one of them goes down. Register for the free webinar.
What happened on October 20, 2025
A latent race condition in Amazon DynamoDB’s DNS automation left the DynamoDB endpoint in us-east-1 with an empty DNS record, and everything that resolved that name failed. According to the AWS post-event summary, the event ran about 15 hours and spread to EC2 instance launches and Network Load Balancers. Recovery that needed new instances was blocked for hours, because launching instances depended on the same impaired services.
Teams that had spread replicas across availability zones still went down. Every zone in the region depended on the same regional endpoint.
Why one region, or one provider, isn’t enough
Cloud failures hit three blast radii, and each needs a different kind of redundancy:
- A zone: a facility or network fault. Replicas across zones cover it.
- A region: a regional service fails, like DynamoDB in us-east-1. Only a second region covers it.
- A whole provider: a global control plane, edge network, or account layer fails. Only a second provider covers it.
Most teams are protected against the first, partly against the second, and not at all against the third. The full breakdown of every major cloud failure since 2025 shows each provider failing in a different layer.
What you’ll see in the webinar
- The outage, recreated live: the same failure, in a real environment, as it happens.
- What active-active looks like during it: a workload running in more than one location keeps serving from the healthy ones while one location is down.
- What it takes to get there: how teams run the container images they already have across regions and providers without a rewrite or a platform team.
- Live Q&A about your own architecture.
Why we’re the ones showing it
Control Plane combines any cloud, neocloud, and bare metal into one virtual cloud, so you stay up when others are down. Workloads run active-active across every location in a Global Virtual Cloud, with a 99.999% availability SLA for workloads running at least two replicas in at least two locations.
On October 20, 2025, 20% of Control Plane customers had us-east-1 in their Global Virtual Clouds. Their workloads were active and running in healthy locations within 10 seconds, with no customer downtime, according to Control Plane internal incident telemetry.
Who should attend
- CTOs and heads of engineering who own uptime commitments to customers
- SRE and platform teams running production in one region or on one provider
- Anyone who was paged on October 20, 2025, and doesn’t want to be again
Webinar details
- When: Tuesday, October 20, 2026, 11:00 AM PT
- Where: online (Zoom)
- Cost: free
- Register: save your spot
Next step: Register for the free webinar, or talk to the Control Plane team about your own setup.